PulseAugur
EN
LIVE 02:45:30

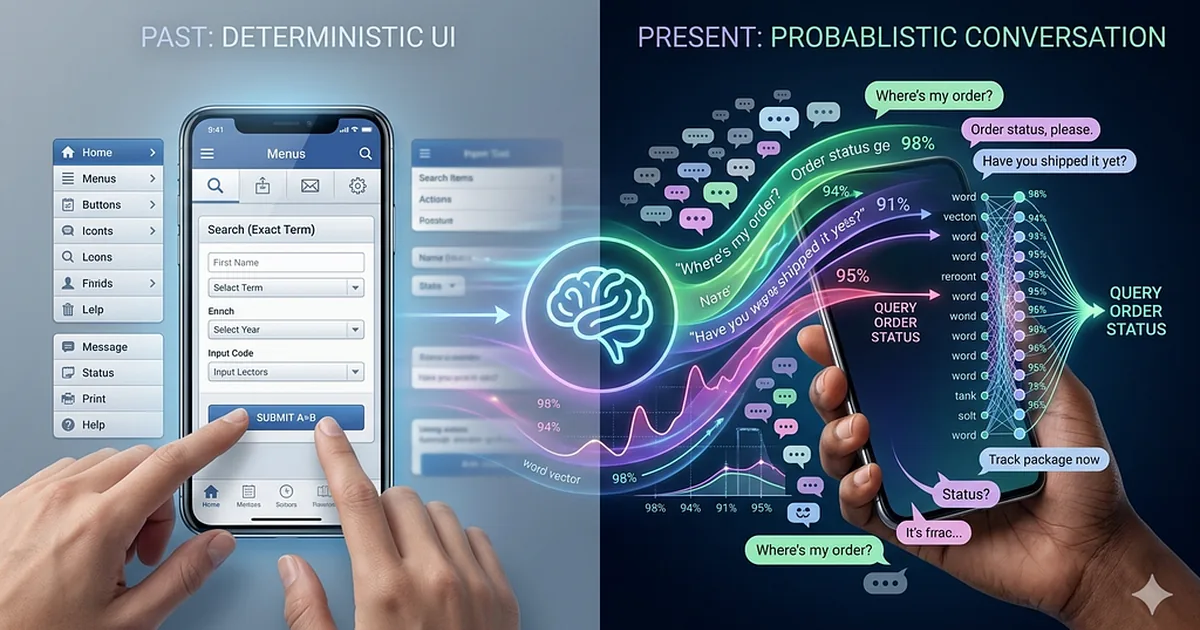
Semantic caching tackles LLM costs for varied user queries

Developers are increasingly facing challenges with the probabilistic nature of natural language interactions in AI systems, particularly with large language models (LLMs). A common issue is the cost and latency incurred by running full inference for semantically identical queries phrased differently. To address this, the concept of semantic caching has emerged, which goes beyond simple exact-match caching. Semantic caching aims to identify and store responses for queries with similar intent, even if the wording varies, thereby reducing redundant computations and associated costs. AI

IMPACT Semantic caching can significantly reduce operational costs and improve response times for applications relying on LLMs by intelligently reusing previous computations.

RANK_REASON The article discusses a technical implementation and mathematical concept for optimizing LLM usage, fitting the research category. [lever_c_demoted from research: ic=1 ai=1.0]

Read on Towards AI →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
Semantic caching tackles LLM costs for varied user queries

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The article discusses a technical implementation and mathematical concept for optimizing LLM usage, fitting the research category. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
152 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. Towards AI TIER_1 English(EN) · Vatsala Singh ·

    Semantic Cache: The Math of ‘Close Enough’

    <figure><img alt="" src="https://cdn-images-1.medium.com/max/1024/1*pOLa6q5xvwmSoudAABVBnA.png" /></figure><p>Human-machine interaction has evolved significantly over the past few years. There was a time when the user interface was one of the key determinants of how well a digita…