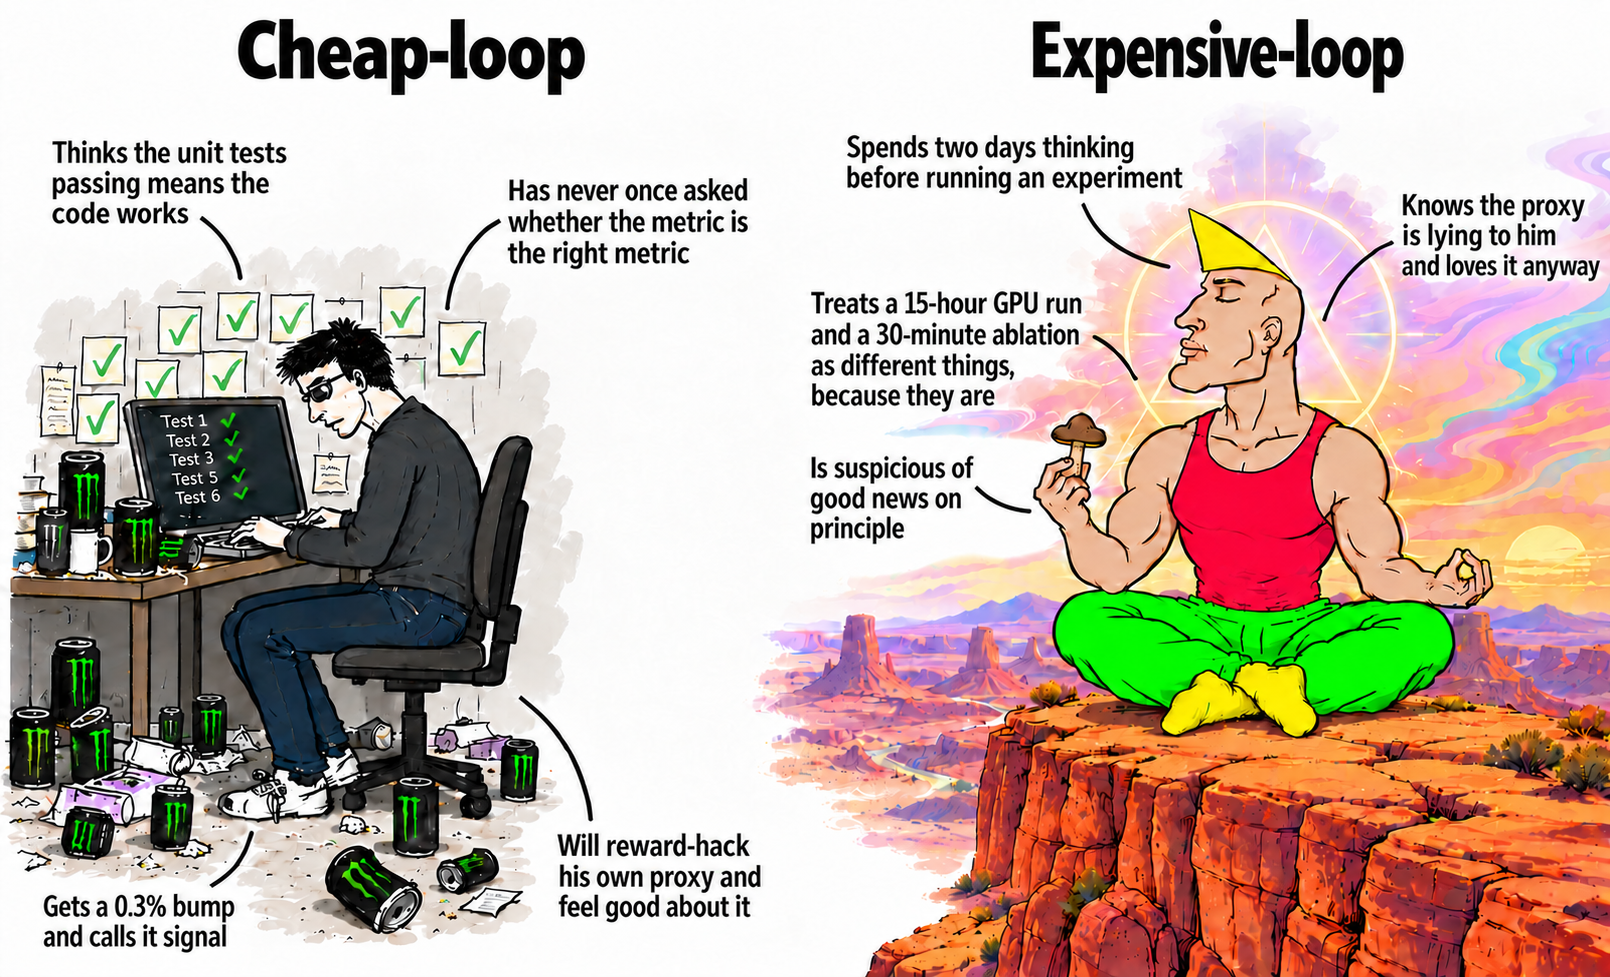
The "expensive-loop problem" describes a scenario in AI development where a model is repeatedly trained on its own outputs, leading to a degradation of quality and a potential loss of grounding in reality. This occurs when an AI system generates data, which is then used to train a subsequent version of the same AI, creating a feedback loop. The issue is exacerbated by the high cost of human data labeling and the desire for continuous model improvement, pushing developers towards self-supervised or self-generated data training methods. Addressing this problem may require novel approaches to data curation, validation, and the integration of external, real-world feedback. AI
IMPACT Highlights a potential pitfall in AI training that could impact model reliability and performance.
RANK_REASON The item discusses a conceptual problem in AI development rather than a specific event or release.
AI-generated summary · Google Gemini · from 1 sources. How we write summaries →