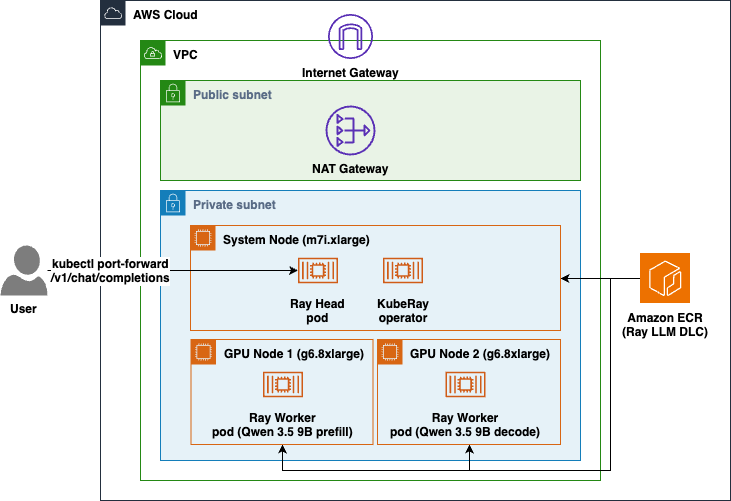
AWS has introduced new Ray LLM Deep Learning Containers designed to simplify the deployment of large language models across multiple GPU nodes on Amazon Elastic Kubernetes Service (Amazon EKS). These containers bundle Ray Serve, NVIDIA Inference Transfer Library, and the Elastic Fabric Adapter stack, offering an OpenAI-compatible API without requiring custom application code. This setup enables disaggregated inference, separating the compute-intensive prefill phase from the memory-bandwidth-bound decode phase to enhance performance and predictability, especially for high-concurrency multi-turn workloads. AI
IMPACT Simplifies deployment of large language models across multiple GPUs, potentially lowering the barrier for complex inference tasks.
RANK_REASON This is a product announcement from a cloud provider about tooling for LLM inference, not a new frontier model release.
Read on AWS Machine Learning Blog →
- Amazon EKS
- Amazon Elastic Kubernetes Service
- AWS
- AWS Deep Learning Containers
- Efa
- Elastic Fabric Adapter
- NIXL
- NVIDIA Inference Transfer Library
- Ray
- Ray LLM Deep Learning Containers
- Ray Serve
- Ethernet
- graphics processing unit
- remote direct memory access
AI-generated summary · Google Gemini · from 2 sources. How we write summaries →