PulseAugur
EN
LIVE 22:01:05

Anyscale details 90% cost reduction for coding agents via self-hosted LLMs

Anyscale has published a guide detailing how to significantly reduce the costs associated with running coding agents, by up to 90%. The approach involves self-hosting Large Language Models (LLMs) using their platform, which integrates Ray Serve and vLLM, rather than relying on per-token API pricing. This method not only offers substantial cost savings but also provides enhanced data privacy and performance improvements, such as faster compilation times and higher request throughput. AI

IMPACT Enables organizations to significantly cut operational costs for AI-powered coding agents and gain greater control over data privacy.

RANK_REASON The article provides a guide and technical details for optimizing LLM serving infrastructure, which is a tool-oriented topic rather than a core model release or research breakthrough.

Read on Mastodon — mastodon.social →

AI-generated summary · Google Gemini · from 2 sources. How we write summaries →
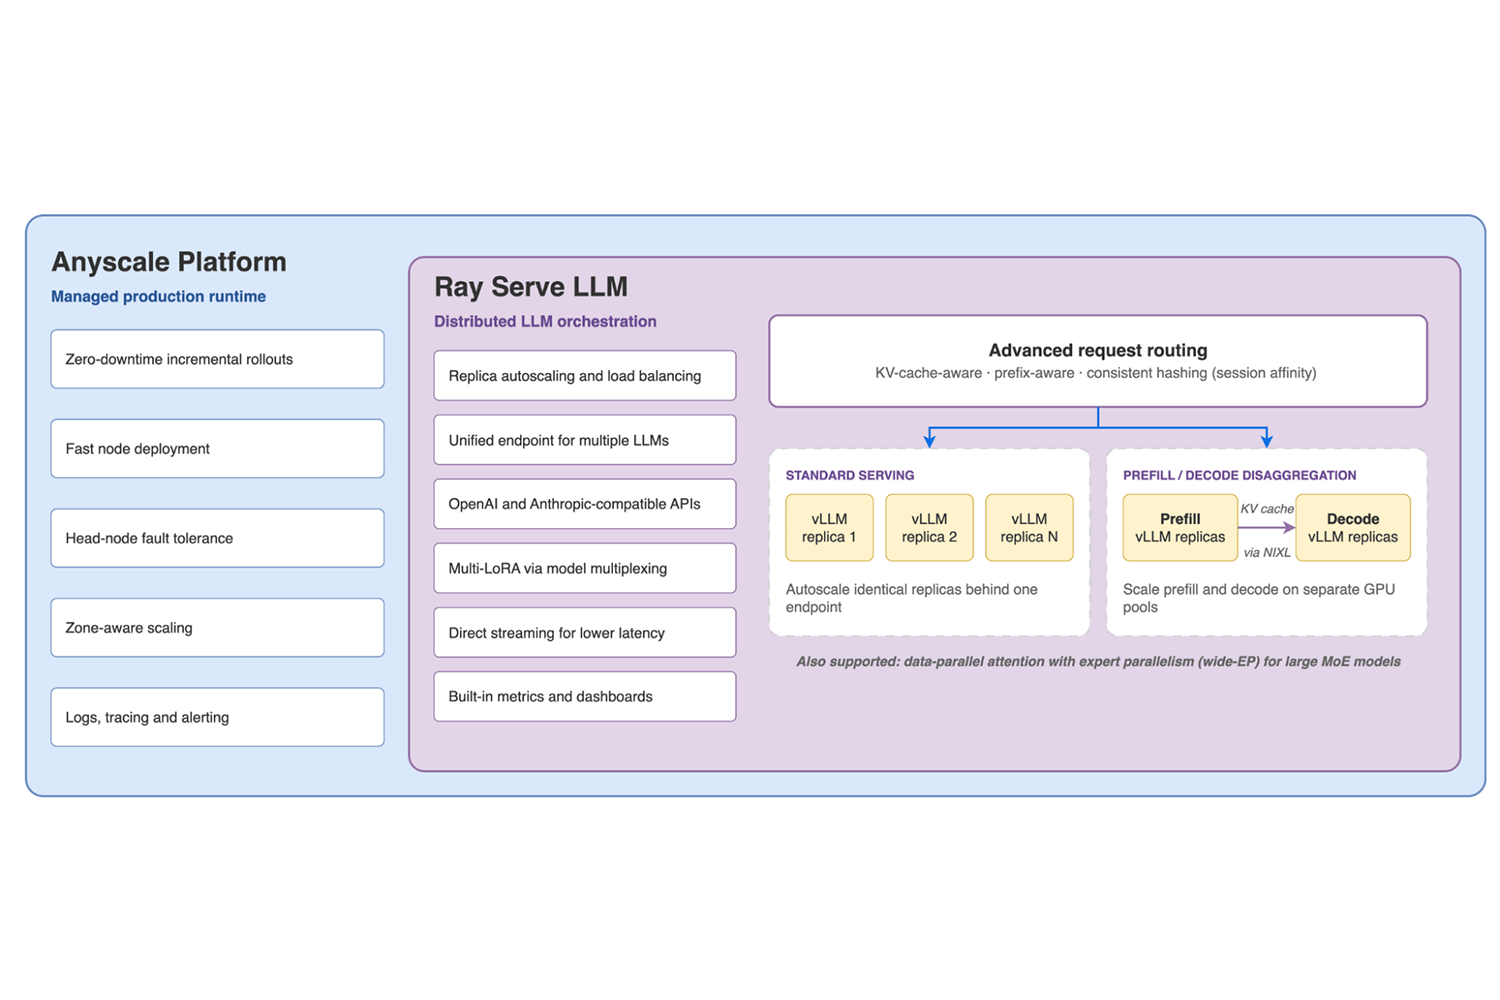
Anyscale details 90% cost reduction for coding agents via self-hosted LLMs

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The article provides a guide and technical details for optimizing LLM serving infrastructure, which is a tool-oriented topic rather than a core model release or research breakthrough.
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
6 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [2]

  1. Anyscale blog TIER_1 English(EN) ·

    Cut coding agent costs by 90%: Secure LLM serving with Ray + vLLM on Anyscale

    Serve coding agents on your own GPUs. A guide to Ray Serve and vLLM on Anyscale, from engine tuning to cache-aware routing, with measured results.

  2. Mastodon — mastodon.social TIER_1 English(EN) · sipirtu ·

    The article explains how to cut coding agent costs by 90 percent by using secure LLM serving with Ray and vLLM on Anyscale. Source: Anyscale https:// anyscale.c

    The article explains how to cut coding agent costs by 90 percent by using secure LLM serving with Ray and vLLM on Anyscale. Source: Anyscale https:// anyscale.com/blog/run-coding-a gents-on-your-own-gpus # AI