PulseAugur
EN
LIVE 18:39:38

Perplexity unveils new contextual embedding model, setting SOTA on benchmarks

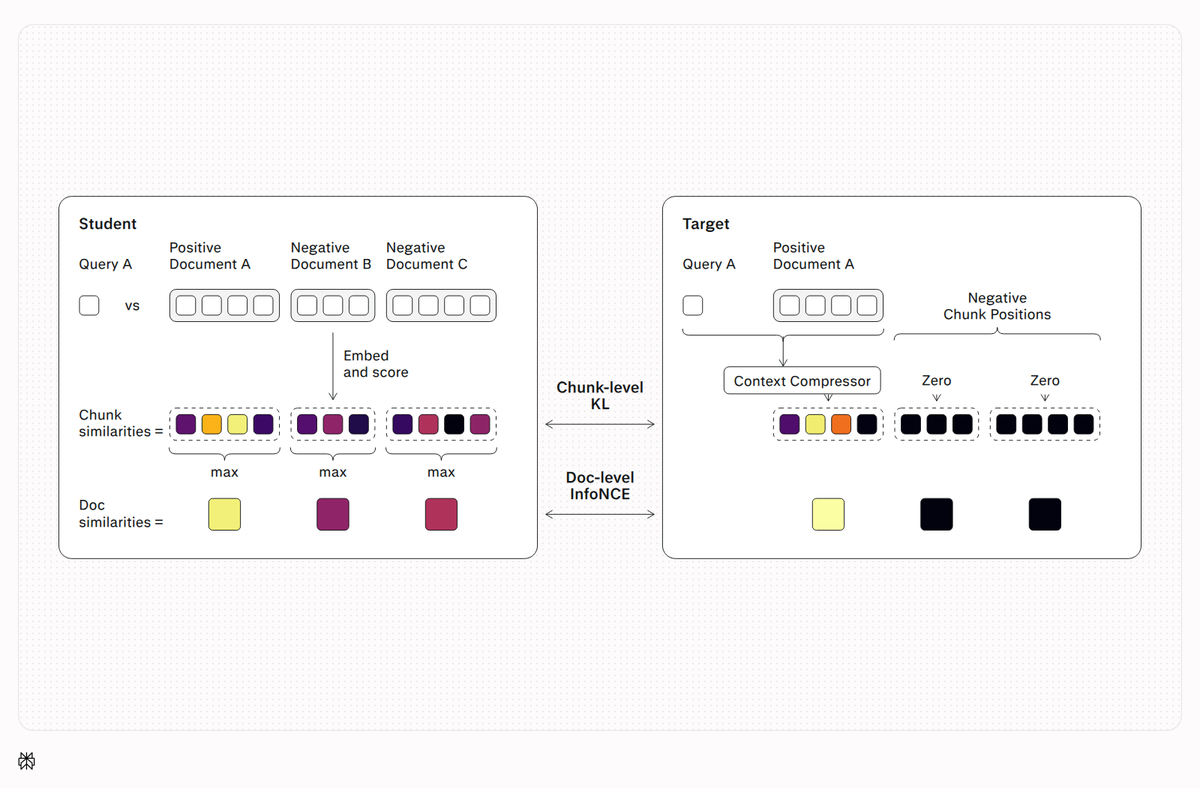
Perplexity has introduced a new contextual embedding model, pplx-embed-v2-context-9b-preview, which sets a new state-of-the-art on the ConTEB and context-bench benchmarks. This model encodes each document chunk with the entire document in view, addressing limitations of traditional chunking methods. It achieves this by distilling relevance from a query-aware context compression model and offers a more storage-efficient vector representation compared to models like voyage-context-4. AI

IMPACT Sets new SOTA on retrieval benchmarks, potentially improving RAG systems and offering more efficient vector storage.

RANK_REASON Frontier-lab model release with system card.

Read on X — Perplexity →

AI-generated summary · Google Gemini · from 7 sources. How we write summaries →
Perplexity unveils new contextual embedding model, setting SOTA on benchmarks

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Frontier Release
Frontier-lab model release with system card.
Source corroboration
7 independent sources
Strong cross-source corroboration — multiple independent publishers covered this within the clustering window.
Topics
model release, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
7 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [7]

  1. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    View pplx-embed-v2-context-9b-preview on Hugging Face:

    View pplx-embed-v2-context-9b-preview on Hugging Face: https://t.co/EeqI2xCFOl

  2. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    On ConTEB, the preview has the highest average nDCG@10 of the models tested, though not on every task.

    On ConTEB, the preview has the highest average nDCG@10 of the models tested, though not on every task. It also beats voyage-context-4 on chunk retrieval while using 8x less storage per vector: 1 KB (1024 dims, int8) vs 8 KB (2048, float32). https://t.co/PsyAwyU0Zo

  3. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    pplx-embed-v2-context-9b-preview leads on Answer and Evidence retrieval at every cutoff.

    pplx-embed-v2-context-9b-preview leads on Answer and Evidence retrieval at every cutoff. Document retrieval is closer, with our context v1 4B slightly ahead at Document@3 and Document@5. https://t.co/9DrBG7sxPp

  4. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    context-bench is a benchmark for context-aware retrieval, created and privately held by @turbopuffer. Its queries, documents and capabilities are inspired by co

    context-bench is a benchmark for context-aware retrieval, created and privately held by @turbopuffer. Its queries, documents and capabilities are inspired by conversations with turbopuffer customers. It has 2,099 queries and 38,894 documents. We submitted for blind evaluation. h…

  5. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    We overcome gold-chunk supervision limits by distilling relevance from our query-aware context compression model.

    We overcome gold-chunk supervision limits by distilling relevance from our query-aware context compression model. It scores every document token against the query. Aggregated into chunk-level targets, those scores train the embedder to retrieve answer and supporting chunks. http…

  6. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    Retrieval systems often split long documents into chunks, but this strips away the surrounding context.

    Retrieval systems often split long documents into chunks, but this strips away the surrounding context. Contextual embedding models fix this by encoding the whole document once and pooling chunk vectors afterward. They are usually trained on one gold chunk per query.

  7. X — Perplexity TIER_1 English(EN) · perplexity_ai ·

    We built a new way to train contextual embedding models, which encode each chunk of a document with the whole document in view.

    We built a new way to train contextual embedding models, which encode each chunk of a document with the whole document in view. pplx-embed-v2-context-9b-preview sets a new state of the art on ConTEB and @turbopuffer's new, privately held context-bench. https://t.co/tkBUEjWVio h…