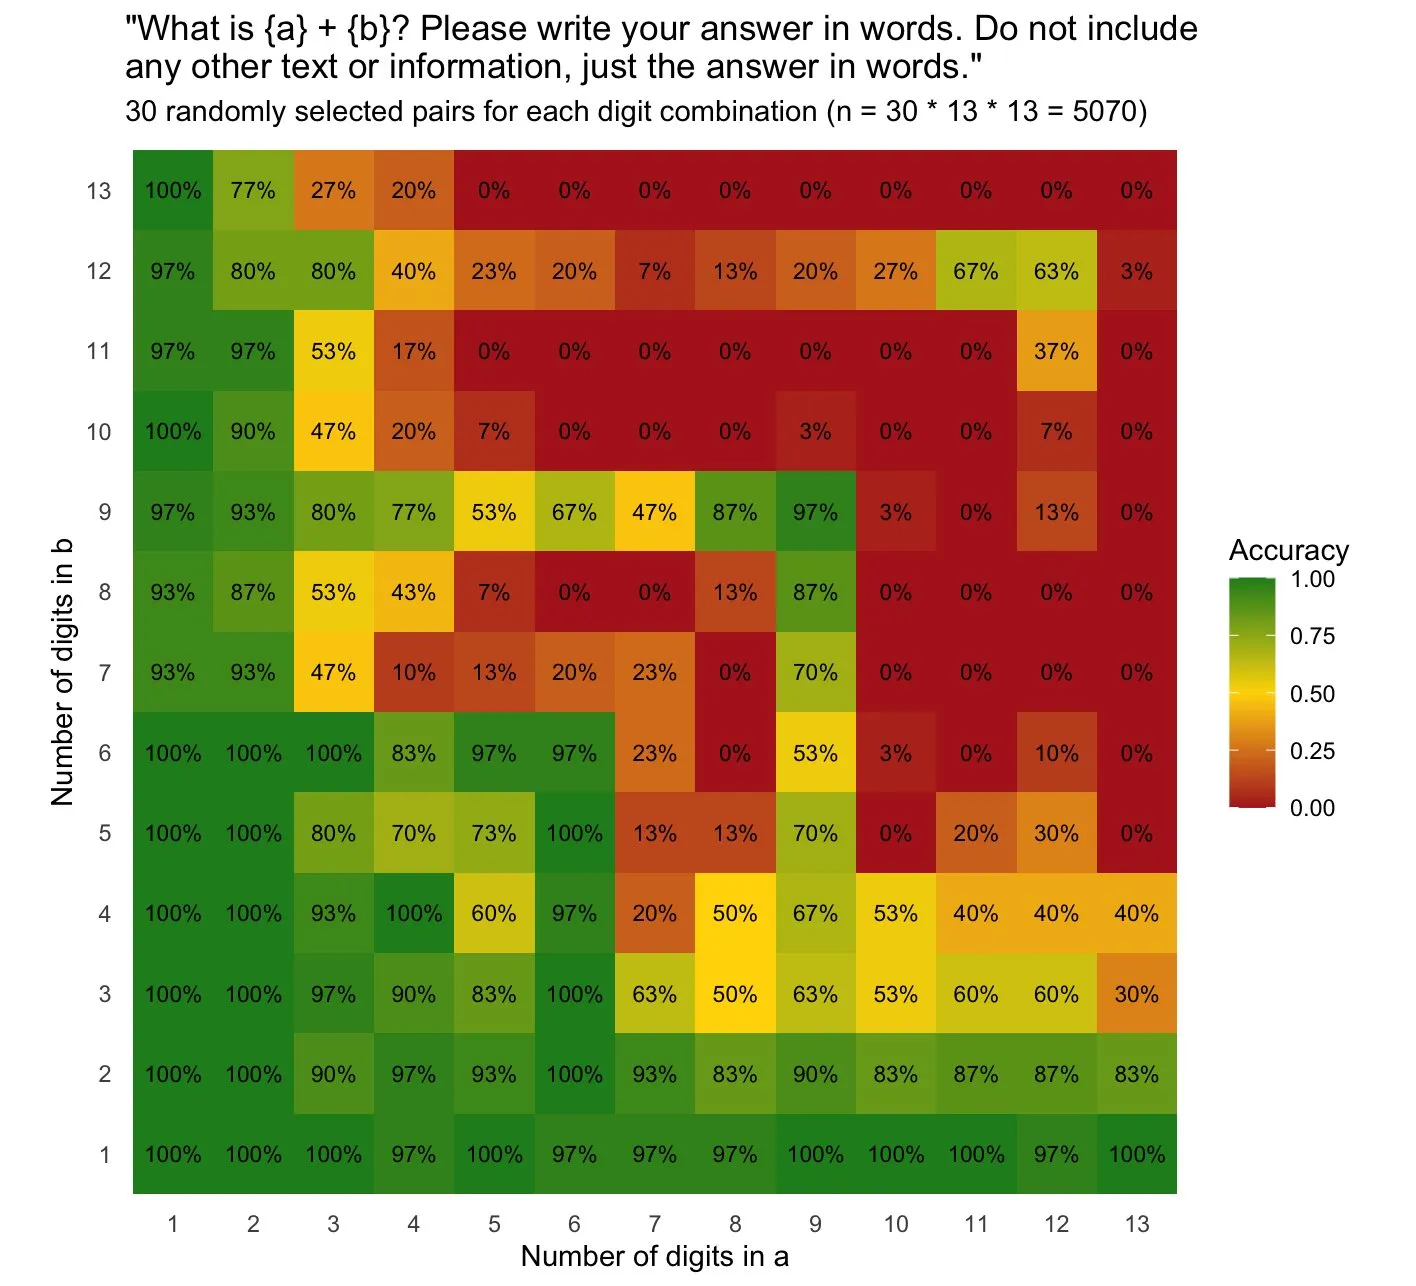
Simon Willison documented an experiment comparing the ability of different AI models to perform addition and express the result in words. Initially inspired by a GPT-4o test from two years prior, Willison re-ran the experiment on local hardware using Qwen3.8 27B. The Qwen3.8 model demonstrated a high degree of accuracy, correctly answering 167 out of 169 one-shot attempts when reasoning was enabled. AI
IMPACT Demonstrates improved numerical reasoning and word-based output capabilities in LLMs.
RANK_REASON The cluster details an experiment comparing AI model capabilities on a specific task, fitting the research category.
- Bluesky
- Codex Remote
- Colin Frasier
- DGX Spark
- GPT-4o
- GPT-6 Astra
- OpenAI DevDay 2026
- Qwen3.8
- Qwen3.8-27B-Q4_K_M.gguf
- Simon Willison
AI-generated summary · Google Gemini · from 2 sources. How we write summaries →