PulseAugur
EN
LIVE 20:17:55
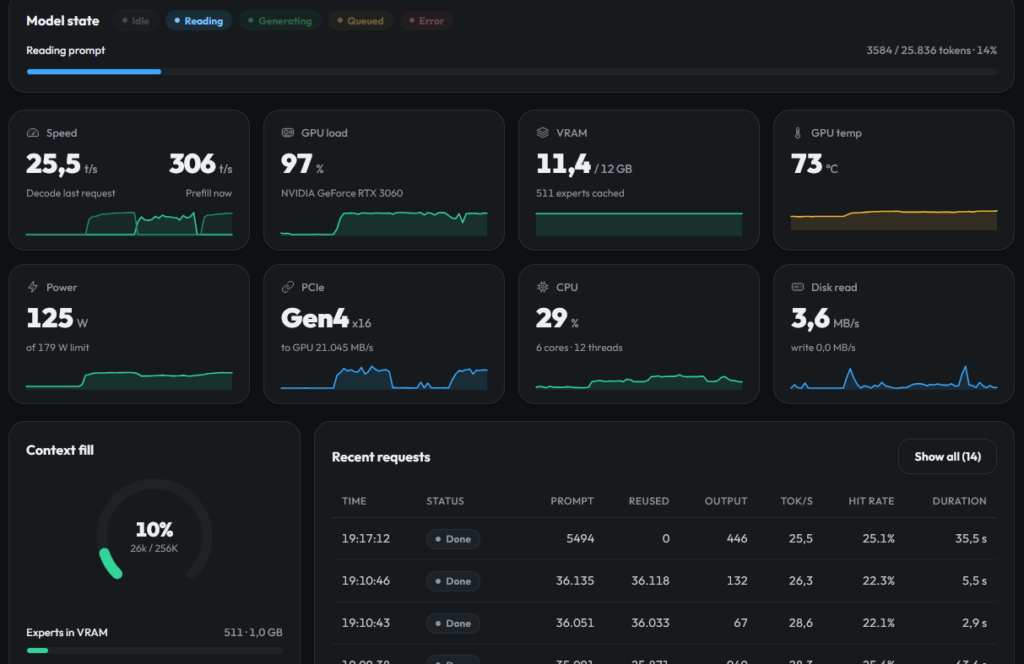
Italiano(IT) Ho provato Strata con il modello Coder su una RTX 3060 da 12 GB: circa 30 token al secondo, contesto ampio e una cache efficace. Una prima esperienza con OpenCo

Strata project enables large local LLM execution on consumer GPUs

The Strata project enables running large language models like Qwen3.8-Flash-Next locally on consumer hardware, including GPUs with 12GB VRAM. It achieves this by distributing the model's workload across the GPU, CPU, RAM, and SSD, and utilizes a Mixture of Experts architecture to activate only necessary components for each token. Initial testing on a RTX 3060 showed promising speeds of around 30 tokens per second for generation and effective cache utilization, making it a viable option for local coding tasks. AI

IMPACT Enables local execution of large models on consumer hardware, potentially reducing reliance on cloud inference for coding tasks.

RANK_REASON The article describes a project that enables running existing LLMs on consumer hardware, rather than a new model release or significant industry shift.

Read on Mastodon — mastodon.social →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
Strata project enables large local LLM execution on consumer GPUs

How we ranked this

Signal score
9 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The article describes a project that enables running existing LLMs on consumer hardware, rather than a new model release or significant industry shift.
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, model release
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
Breaking (< 6h)
Fresh story with cross-source coverage still developing. Ranking may shift as more sources report.

Full methodology in our editorial standards.

COVERAGE [1]

  1. Mastodon — mastodon.social TIER_1 Italiano(IT) · [email protected] ·

    I tried Strata with the Coder model on a 12GB RTX 3060: about 30 tokens per second, large context, and an effective cache. A first experience with OpenCo

    Ho provato Strata con il modello Coder su una RTX 3060 da 12 GB: circa 30 token al secondo, contesto ampio e una cache efficace. Una prima esperienza con OpenCode che, pur con qualche compromesso nella qualità, rende il coding locale molto più convincente. #ai #AILocale #llm #Ope…