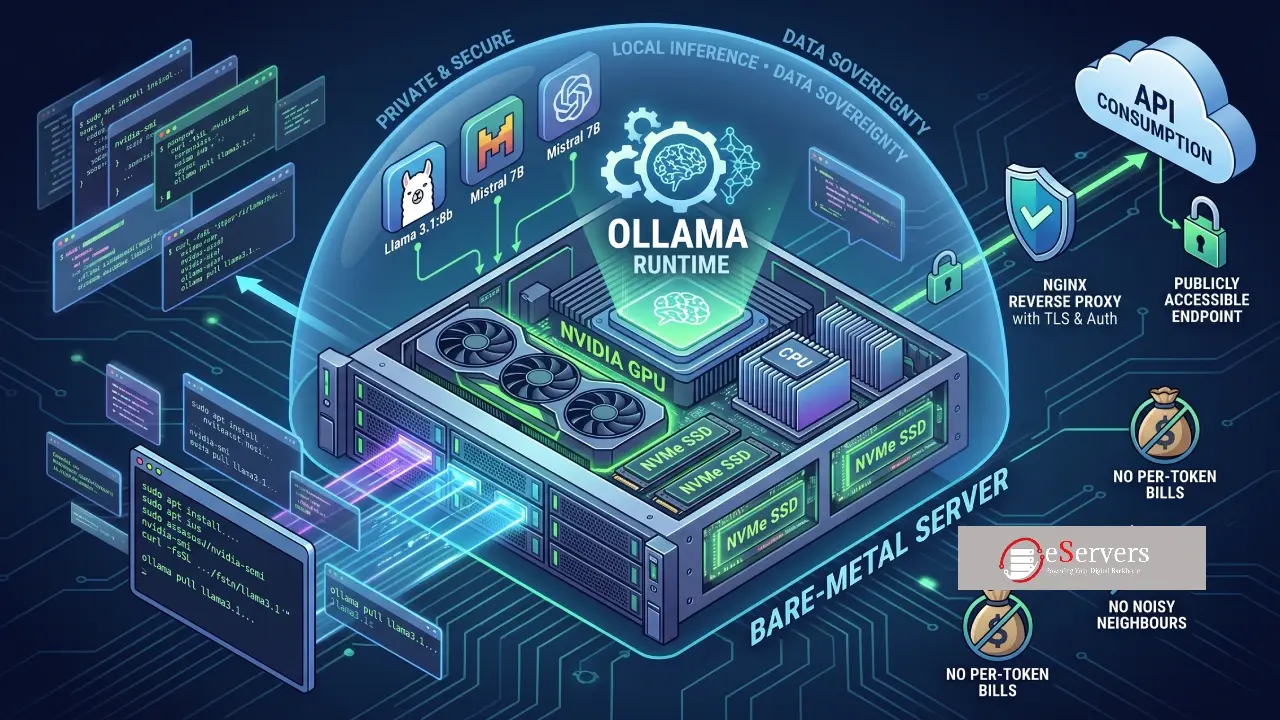
The post advocates for enhanced AI data privacy by running open-weight Large Language Models (LLMs) locally using Ollama on bare-metal GPU servers. This approach aims to maximize VRAM utilization and avoid the overhead associated with hypervisors. The author also provides a tutorial for secure deployment on Ubuntu Linux. AI
IMPACT Enables users to maintain control over sensitive AI data by running models locally, bypassing external API risks.
RANK_REASON The item discusses a tool (Ollama) for running LLMs locally, which is a specific application rather than a core AI release or significant industry event.
Read on Mastodon — mastodon.social →
AI-generated summary · Google Gemini · from 1 sources. How we write summaries →