PulseAugur
EN
LIVE 22:26:46

Researchers explore "evaluation awareness" in smaller AI models

Researchers John Robertson and Zach Perlman explored the concept of "evaluation awareness" in smaller AI models. Their work suggests that these models may not fully grasp the context or purpose of the evaluations they undergo. This lack of awareness could impact the reliability and interpretability of their performance metrics. AI

IMPACT Understanding how smaller models interpret evaluations is crucial for developing more reliable and interpretable AI systems.

RANK_REASON The item discusses a research paper or concept explored by researchers. [lever_c_demoted from research: ic=1 ai=1.0]

Read on LessWrong (AI tag) →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
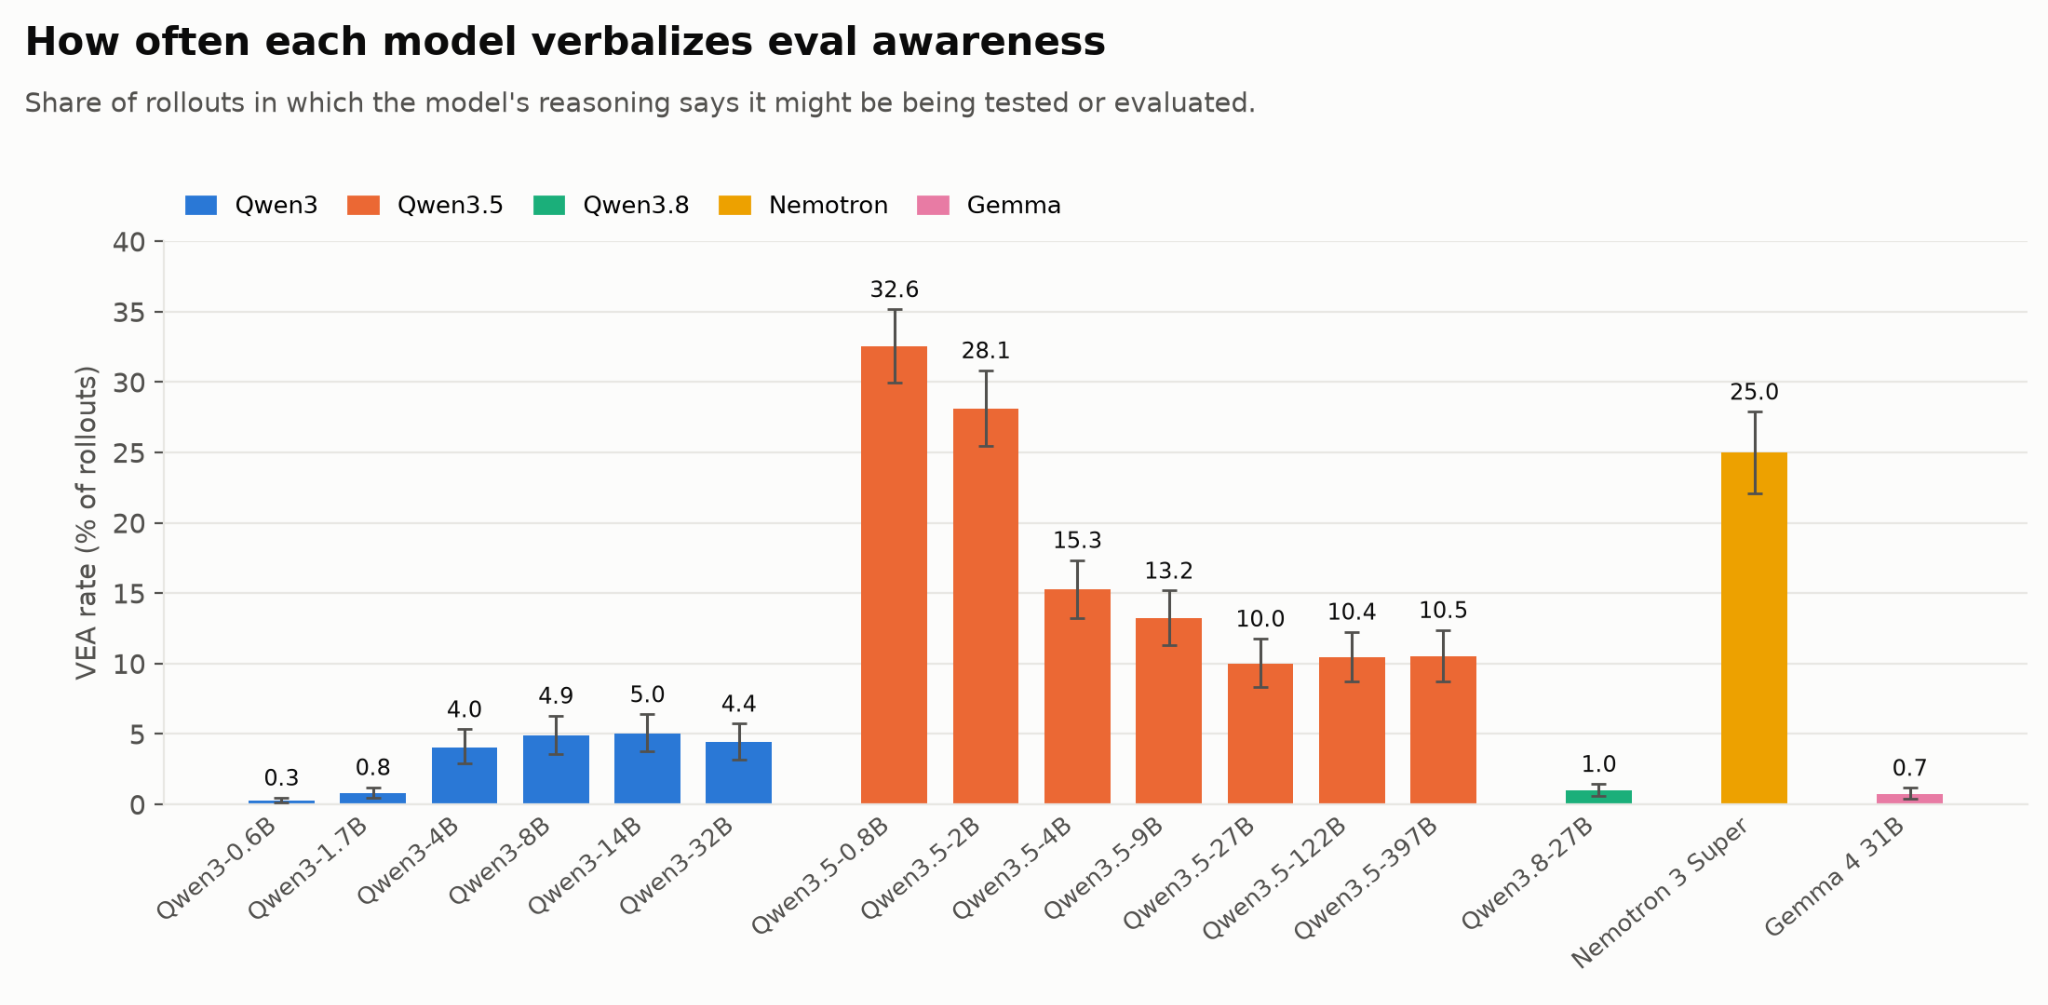
Researchers explore "evaluation awareness" in smaller AI models

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The item discusses a research paper or concept explored by researchers. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
10 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. LessWrong (AI tag) TIER_1 English(EN) · John Robertson ·

    Evaluation Awareness in Small(ish) Models

    <h2><span style="white-space: pre-wrap;">TL;DR</span></h2><p><i><span style="white-space: pre-wrap;">We seek to identify open source reasoning models which are both small enough for white-box interpretability and display evaluation-gaming behavior. We find that how often models v…