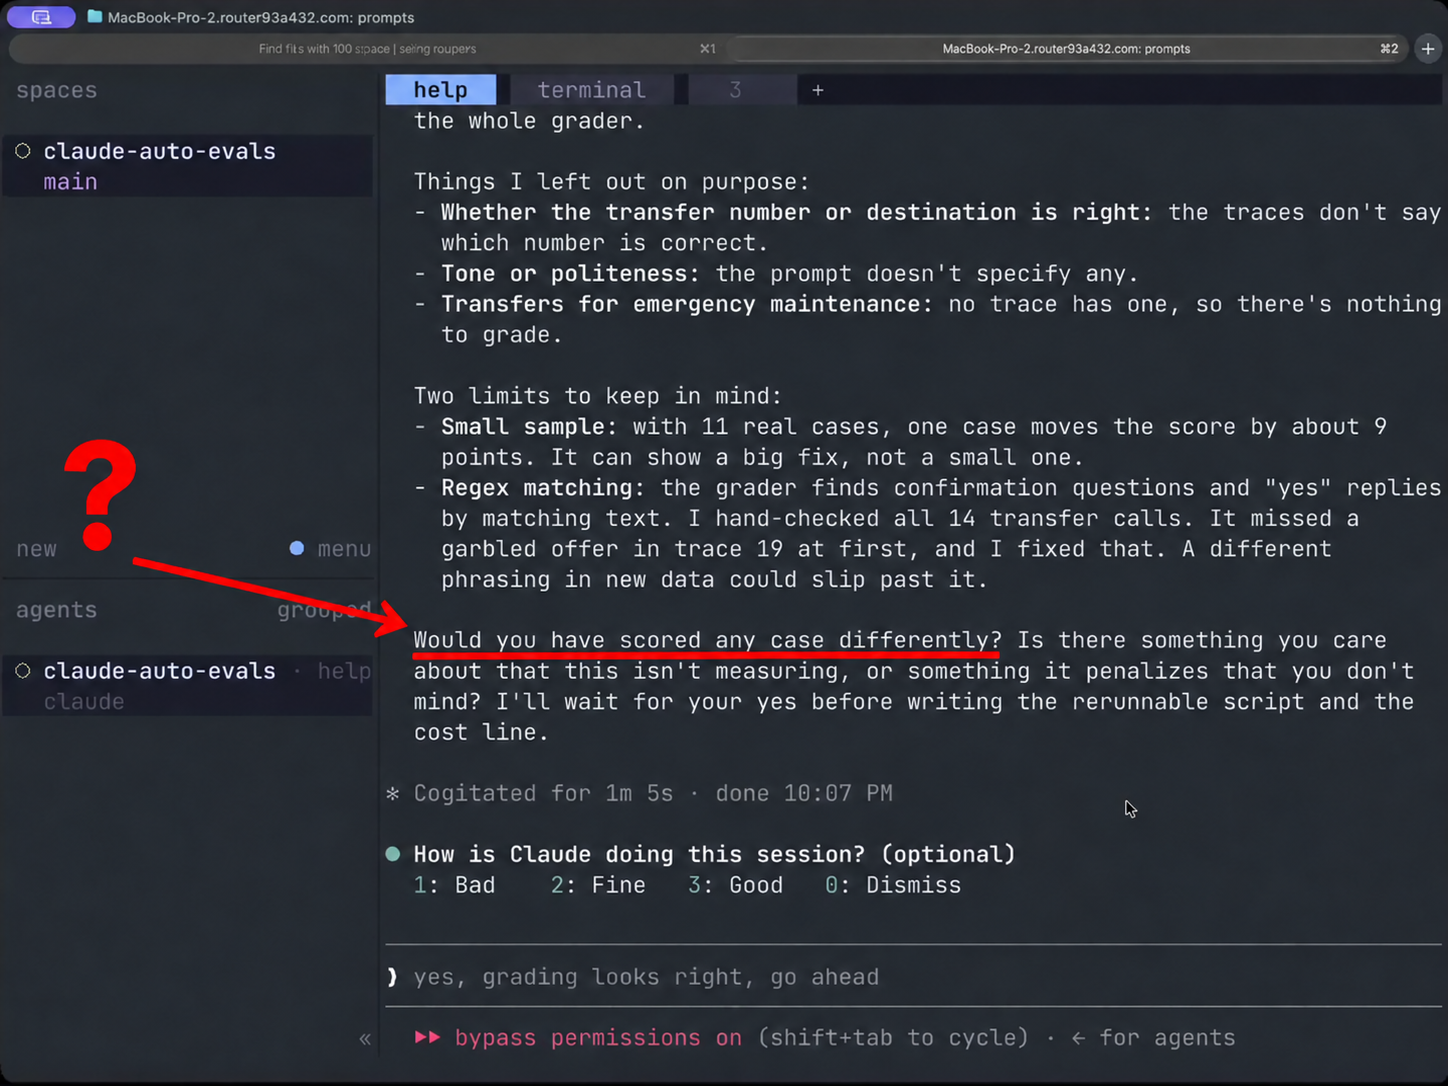
Hamel Dev has released a review of Anthropic's new auto-evaluation tool for Claude Code, noting both its strengths and weaknesses. The tool, integrated into the claude-api plugin, aims to assist developers in building and refining evaluations for their applications. While the tool demonstrated an impressive ability to discover a variety of issues, including human handoff and formatting problems, the reviewer found its workflow to be too prescriptive, pushing users to create evals before analyzing data and validating judgments without sufficient context. The reviewer also suggested that the evaluator's scope was too broad, bundling multiple failure types into a single assessment. AI
IMPACT This review offers insights into the practical usability of AI evaluation tools, potentially influencing how developers approach model assessment and refinement.
RANK_REASON This is a review of a tool, not a release announcement or a significant industry event.
AI-generated summary · Google Gemini · from 1 sources. How we write summaries →