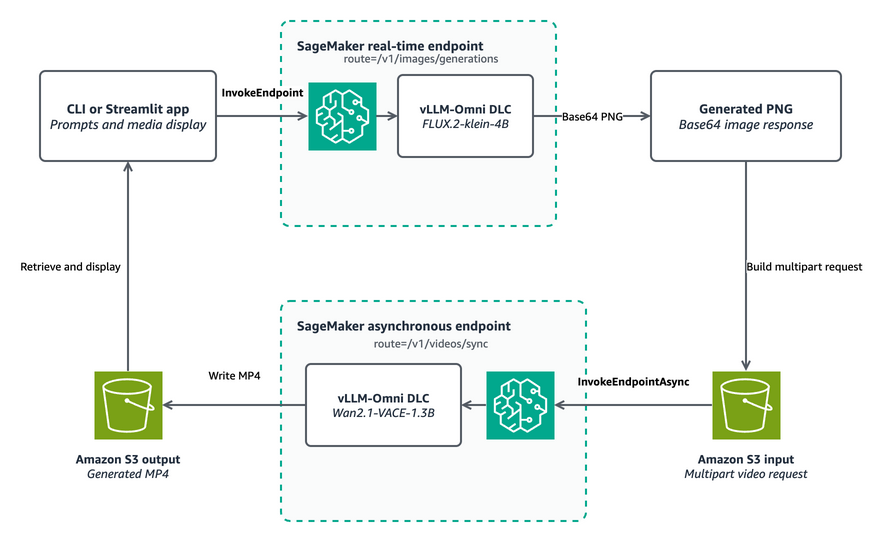
AWS has introduced a new capability on SageMaker AI that allows users to generate images and videos from text prompts. This is achieved by deploying two distinct endpoints from the same AWS vLLM-Omni Deep Learning Container: one for real-time image generation using FLUX.2-klein-4B and another for asynchronous video generation with Wan2.1-VACE-1.3B. The process involves sending a text prompt to create an image, which is then used along with a motion prompt to generate a video, with the final output stored in Amazon S3. AI
IMPACT Enables users to generate images and videos directly on AWS SageMaker AI, streamlining multi-modal content creation workflows.
RANK_REASON Article describes a new capability and workflow on an existing platform (SageMaker AI) using specific models and containers, rather than a novel model release or fundamental research.
Read on AWS Machine Learning Blog →
- Amazon S3
- Amazon SageMaker AI
- AWS
- AWS vLLM-Omni Deep Learning Container
- FLUX.2-klein-4B
- OpenAI
- SageMaker AI
- streamlit
- vLLM-Omni
- Wan2.1-VACE-1.3B
AI-generated summary · Google Gemini · from 1 sources. How we write summaries →