PulseAugur
EN
LIVE 20:07:43

LLM KV Caching Explained: Speed vs. Memory Tradeoff

Large language models utilize KV caching to accelerate inference by storing previously computed key and value vectors, rather than recomputing them for each new token. This technique significantly speeds up token generation after an initial, more compute-intensive "prefill" phase where the cache is built. However, KV caching trades increased memory usage for reduced computation, with the cache size growing linearly with context length and potentially exceeding model weights at scale. AI

IMPACT Explains a core LLM inference optimization, impacting model efficiency and deployment costs for operators.

RANK_REASON The cluster explains a technical concept (KV caching) in LLMs, detailing its mechanics and trade-offs, which is characteristic of research or technical documentation.

Read on Medium — MLOps tag →

AI-generated summary · Google Gemini · from 2 sources. How we write summaries →
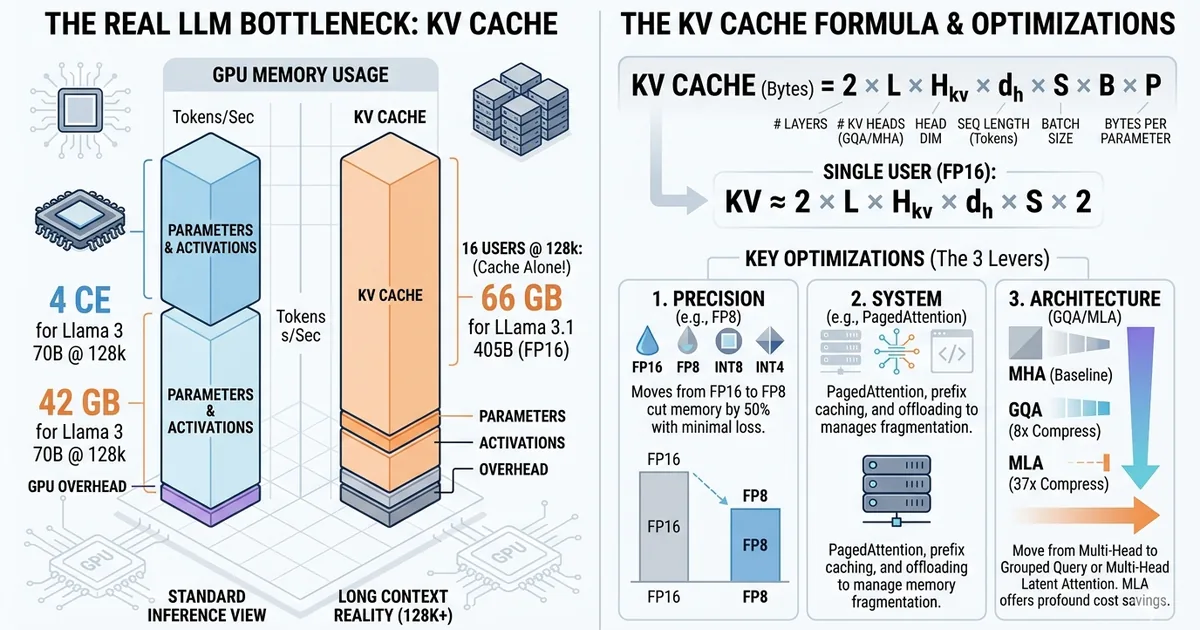
LLM KV Caching Explained: Speed vs. Memory Tradeoff

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
The cluster explains a technical concept (KV caching) in LLMs, detailing its mechanics and trade-offs, which is characteristic of research or technical documentation.
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
infra, model release
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
141 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [2]

  1. Medium — MLOps tag TIER_1 English(EN) · Mahernaija ·

    LLM: How to Calculate KV Cache

    <div class="medium-feed-item"><p class="medium-feed-image"><a href="https://medium.com/@mahernaija/llm-how-to-calculate-kv-cache-e29f095ac2ed?source=rss------mlops-5"><img src="https://cdn-images-1.medium.com/max/1376/1*H0PjsSkDeKbC0ZSz0SbFaw.png" width="1376" /></a></p><p class=…

  2. dev.to — LLM tag TIER_1 Deutsch(DE) · Venkata Manideep Patibandla ·

    KV Caching in LLMs

    <p>You must have seen it every time you use ChatGPT or Claude that the first token takes noticeably longer to appear. Then the rest stream out almost instantly.</p> <p>Behind the scenes, it's a deliberate engineering decision called KV caching, and the purpose is to make LLM infe…