PulseAugur
EN
LIVE 12:05:44

Google's TurboQuant cuts LLM memory use by 6x with no accuracy loss

Google researchers have developed a new technique called TurboQuant that significantly reduces the memory required by large language models. By employing a two-step process involving data rotation and scalar quantization, TurboQuant compresses the KV cache to 3 bits per value, a 6x reduction from the standard 16 bits, without any loss in accuracy. This advancement is crucial for self-hosting LLMs, as the KV cache is a major cost driver for long context windows, and TurboQuant promises to lower infrastructure expenses and improve performance. AI

IMPACT Reduces LLM memory footprint, potentially lowering hosting costs and enabling longer context windows for applications.

RANK_REASON Paper describing a novel algorithm for LLM memory compression presented at a conference. [lever_c_demoted from research: ic=1 ai=1.0]

Read on Towards AI →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
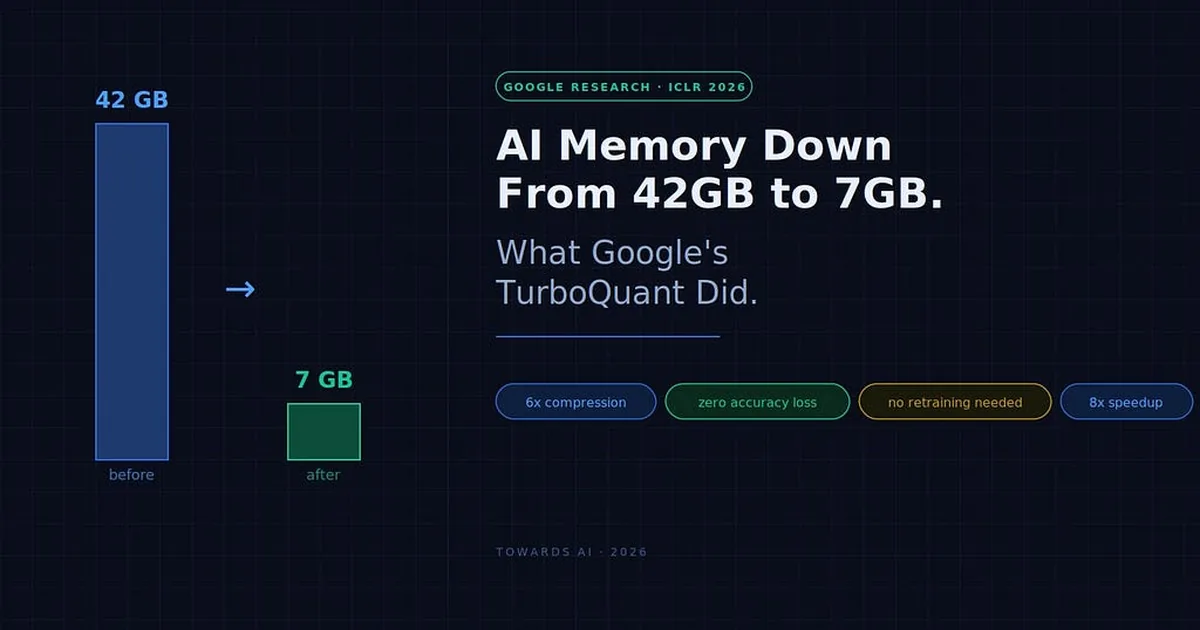
Google's TurboQuant cuts LLM memory use by 6x with no accuracy loss

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
Paper describing a novel algorithm for LLM memory compression presented at a conference. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, paper
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
140 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. Towards AI TIER_1 English(EN) · Yashraj Behera ·

    AI Memory Down From 42GB to 7GB. Here’s What Google’s TurboQuant Actually Did.

    <h4><strong>Google’s TurboQuant compresses LLM memory by 6x with zero accuracy loss. Here’s what that actually means for your infrastructure bill — and what to do about it today.</strong></h4><figure><img alt="" src="https://cdn-images-1.medium.com/max/1024/1*rmeqHlUvSl3UyE5Hk1Fq…