PulseAugur
EN
LIVE 22:18:59

INT8 quantization can slow down AI inference, study finds

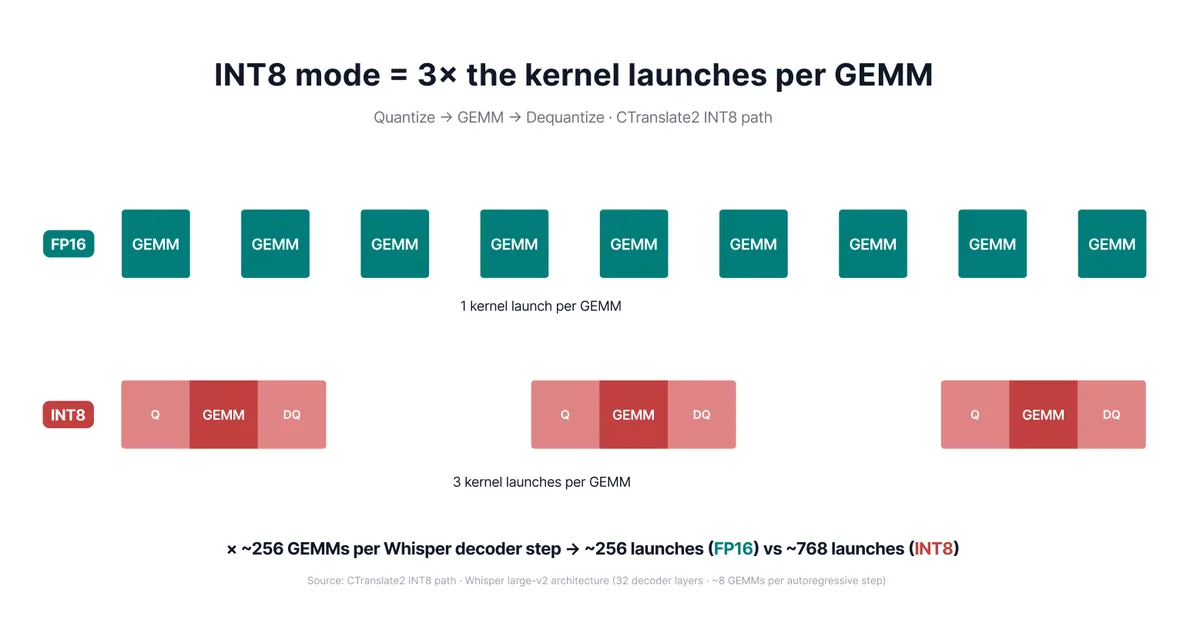
A recent analysis explored the performance of INT8 quantization versus FP16 precision on NVIDIA's Ada Lovelace architecture, specifically using an L40S datacenter GPU and an RTX 4090 consumer card. The findings indicated that under certain real-world inference workloads, INT8 quantization could unexpectedly lead to slower performance compared to FP16. This suggests that the benefits of quantization are not always guaranteed and depend heavily on the specific hardware and task. AI

IMPACT Highlights potential performance pitfalls in model quantization, impacting inference optimization strategies.

RANK_REASON Technical paper analyzing hardware performance and quantization techniques. [lever_c_demoted from research: ic=1 ai=0.7]

Read on Medium — MLOps tag →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
INT8 quantization can slow down AI inference, study finds

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
Technical paper analyzing hardware performance and quantization techniques. [lever_c_demoted from research: ic=1 ai=0.7]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
infra, paper
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
141 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. Medium — MLOps tag TIER_1 English(EN) · Nikodem Dabski ·

    INT8 vs FP16 on Ada Lovelace: When Quantization Makes Inference Slower

    <div class="medium-feed-item"><p class="medium-feed-image"><a href="https://medium.com/@nikodem.dabski/int8-vs-fp16-on-ada-lovelace-when-quantization-makes-inference-slower-3d5e0481cb35?source=rss------mlops-5"><img src="https://cdn-images-1.medium.com/max/1558/1*1GXLCbnZJ0uUly0u…