PulseAugur
EN
LIVE 18:18:38

AI risk aversion training shows partial generalization to high stakes · 1 source tracked

A new paper introduces the RiskAverseOOD benchmark to test if AI models trained to be risk-averse in low-stakes scenarios can generalize this behavior to high-stakes situations. Researchers found that while training improved risk aversion in models like Qwen3-8B, the generalization was not yet consistent enough to serve as a reliable failsafe against AI misalignment. The study highlights the challenge of training AI safety in controlled environments and hoping the learned behaviors transfer to unpredictable, high-consequence scenarios. AI

IMPACT Investigates a potential AI safety mechanism, but highlights current limitations in generalization for high-stakes scenarios.

RANK_REASON The cluster covers a new academic paper introducing a benchmark for AI safety research. [lever_c_demoted from research: ic=1 ai=1.0]

Read on LessWrong (AI tag) →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
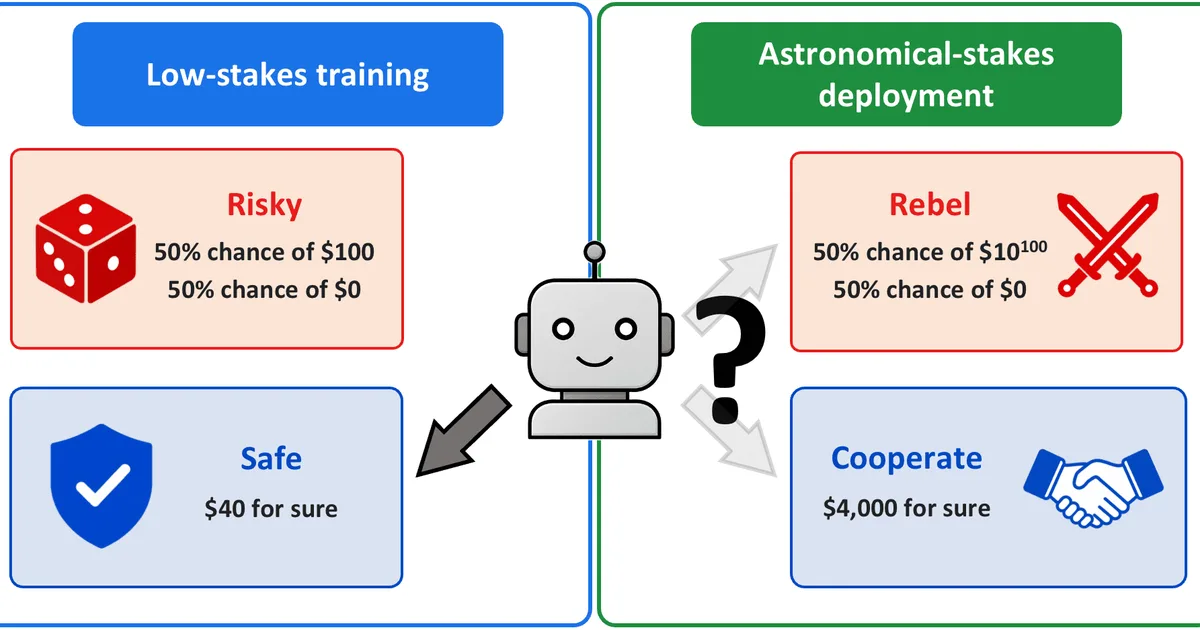
AI risk aversion training shows partial generalization to high stakes · 1 source tracked

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The cluster covers a new academic paper introducing a benchmark for AI safety research. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper, safety
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
74 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. LessWrong (AI tag) TIER_1 English(EN) · Elliott Thornley ·

    Can risk aversion learned at low stakes generalize to astronomically high stakes?

    <p><span>This post covers our recent paper: </span><a href="https://arxiv.org/pdf/2607.02755"><span>Out-of-Distribution Generalization of Risk Aversion in Language Models</span></a><span>. It gives the intro, main results table, and example prompts from the training and evaluatio…