PulseAugur
EN
LIVE 13:51:28

OpenAI finds popular AI coding benchmark SWE-Bench Pro unreliable

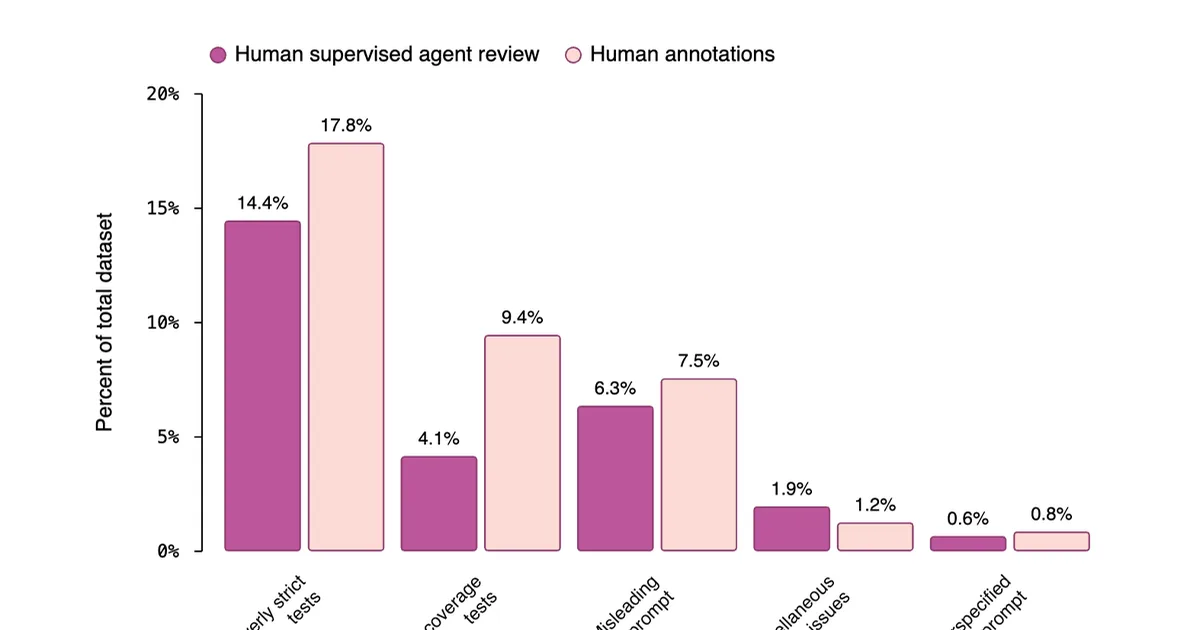
OpenAI has audited SWE-Bench Pro, a widely used benchmark for AI coding capabilities, and found it to be unreliable. Their investigation revealed that a significant portion of the benchmark's tasks are flawed, with issues such as broken problems, hidden requirements, and incomplete grading criteria. Consequently, OpenAI is retracting its recommendation for the research community to use SWE-Bench Pro for evaluating frontier coding performance, emphasizing the need for more robust and trustworthy evaluation methods as coding models advance. AI

IMPACT Highlights the need for more robust and trustworthy benchmarks as AI coding models rapidly improve.

RANK_REASON OpenAI published findings about the unreliability of a widely used AI benchmark.

Read on X — OpenAI →

AI-generated summary · Google Gemini · from 8 sources. How we write summaries →
OpenAI finds popular AI coding benchmark SWE-Bench Pro unreliable

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
OpenAI published findings about the unreliability of a widely used AI benchmark.
Source corroboration
8 independent sources
Strong cross-source corroboration — multiple independent publishers covered this within the clustering window.
Topics
paper, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
79 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [8]

  1. X — OpenAI TIER_1 English(EN) · OpenAI ·

    As coding models improve, evals need to become harder, fairer, and more trustworthy.

    As coding models improve, evals need to become harder, fairer, and more trustworthy. Better benchmarks help the field understand real progress and where the frontier is moving.

  2. X — OpenAI TIER_1 English(EN) · OpenAI ·

    To audit SWE-Bench Pro, we used model-based investigator agents alongside independent reviews from five independent experienced software engineers.

    To audit SWE-Bench Pro, we used model-based investigator agents alongside independent reviews from five independent experienced software engineers. That helped us examine tasks at scale while keeping expert judgment at the center. https://t.co/3PNbk57uvF

  3. X — OpenAI TIER_1 English(EN) · OpenAI ·

    We audited SWE-Bench Pro, one of the most widely used AI coding benchmarks, and found it no longer reliably measures frontier coding capability.

    We audited SWE-Bench Pro, one of the most widely used AI coding benchmarks, and found it no longer reliably measures frontier coding capability. We find 30% of SWE-Bench Pro tasks to be broken, and are retracting our previous recommendation that the research community use it as

  4. X — OpenAI TIER_1 English(EN) · OpenAI ·

    Our audit of SWE-Bench Pro found that a meaningful share of public tasks contain issues that can distort results.

    Our audit of SWE-Bench Pro found that a meaningful share of public tasks contain issues that can distort results. Some correct solutions fail because of hidden requirements, contradictory instructions, overly strict tests, or incomplete grading criteria. https://t.co/s07aJbNks6

  5. X — OpenAI TIER_1 English(EN) · OpenAI ·

    To audit SWE-Bench Pro, we used model-based investigator agents alongside independent reviews from five independent experienced software engineers.

    To audit SWE-Bench Pro, we used model-based investigator agents alongside independent reviews from five independent experienced software engineers. That helped us examine tasks at scale while keeping expert judgment at the center. https://t.co/z0Rz37Q1L3

  6. X — OpenAI TIER_1 English(EN) · OpenAI ·

    As coding models improve, evals need to become harder, fairer, and more trustworthy.

    As coding models improve, evals need to become harder, fairer, and more trustworthy. Better benchmarks help the field understand real progress and where the frontier is moving.

  7. X — OpenAI TIER_1 English(EN) · OpenAI ·

    Our audit of SWE-Bench Pro found that a meaningful share of public tasks contain issues that can distort results.

    Our audit of SWE-Bench Pro found that a meaningful share of public tasks contain issues that can distort results. Some correct solutions fail because of hidden requirements, contradictory instructions, overly strict tests, or incomplete grading criteria. https://t.co/OdIghJH0Xk

  8. X — OpenAI TIER_1 English(EN) · OpenAI ·

    We audited SWE-Bench Pro, one of the most widely used AI coding benchmarks, and found it no longer reliably measures frontier coding capability.

    We audited SWE-Bench Pro, one of the most widely used AI coding benchmarks, and found it no longer reliably measures frontier coding capability. We find the eval to be saturated at a ~70% noise ceiling, and are retracting our previous recommendation that the research community