PulseAugur
EN
LIVE 14:32:50

Fine-tuning LLMs: SFT, RLHF, and DPO Explained

The article compares three primary methods for fine-tuning large language models: Supervised Fine-Tuning (SFT), Reinforcement Learning from Human Feedback (RLHF), and Direct Preference Optimization (DPO). It explains that while SFT is often the most straightforward and suitable for many applications, RLHF and DPO offer more advanced techniques for aligning model behavior with human preferences. The piece aims to clarify the complexities and use cases of each method, guiding users on when to employ more sophisticated approaches. AI

IMPACT Clarifies the nuances of LLM fine-tuning methods, guiding developers on choosing the most effective approach for their specific needs.

RANK_REASON The item is a technical explanation of different model training methods. [lever_c_demoted from research: ic=1 ai=1.0]

Read on Medium — fine-tuning tag →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
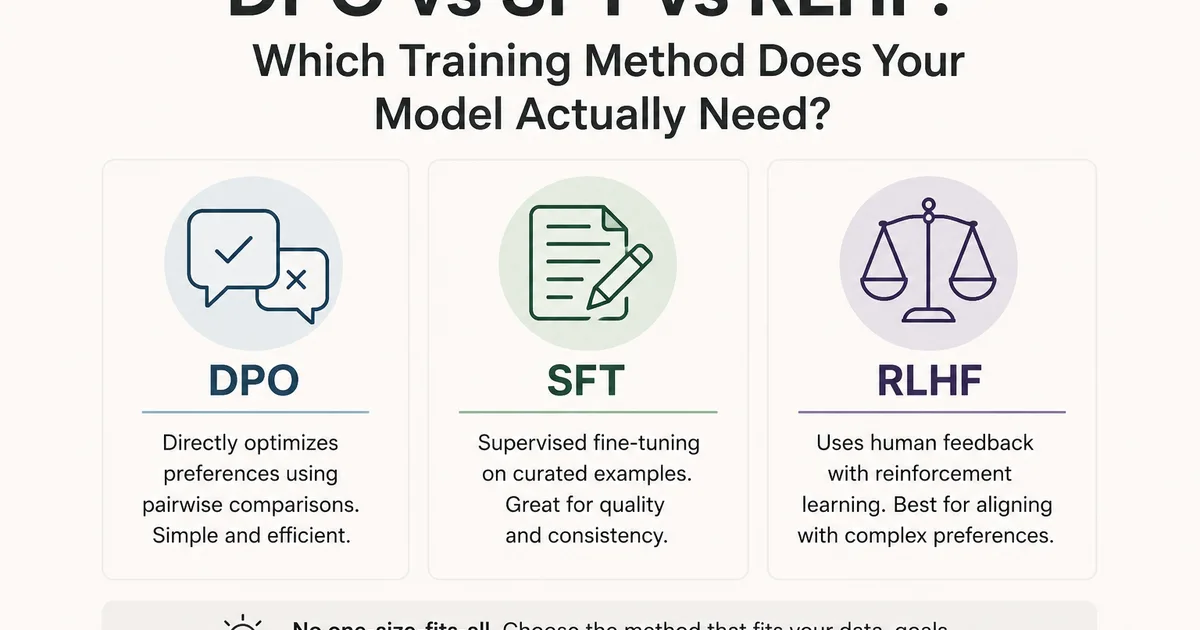
Fine-tuning LLMs: SFT, RLHF, and DPO Explained

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Tool
The item is a technical explanation of different model training methods. [lever_c_demoted from research: ic=1 ai=1.0]
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
paper
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
85 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. Medium — fine-tuning tag TIER_1 English(EN) · Rizwanhoda ·

    DPO vs SFT vs RLHF: Which Training Method Does Your Model Actually Need?

    <div class="medium-feed-item"><p class="medium-feed-image"><a href="https://pub.towardsai.net/dpo-vs-sft-vs-rlhf-which-training-method-does-your-model-actually-need-0c53be82e49d?source=rss------fine_tuning-5"><img src="https://cdn-images-1.medium.com/max/1536/1*QNwGXj26d6AqBJFrAZ…