PulseAugur
EN
LIVE 03:58:47

AI capabilities research seen as a rational safety bet

A LessWrong post argues that focusing on AI capabilities research, rather than safety research, can be a rational choice for agents concerned with safety. The author suggests that if an agent believes capabilities work is more likely to accelerate the arrival of Artificial Superintelligence (ASI) and that this path is ultimately safer, then pursuing capabilities research becomes a logical strategy. The post uses hypothetical scenarios to illustrate how such a belief could lead to prioritizing capability advancements over direct safety work, emphasizing that the perceived safety of a particular research path is subjective and depends on individual beliefs about AI development. AI

IMPACT Suggests a contrarian view on AI safety research, potentially influencing strategic decisions in AI development.

RANK_REASON Opinion piece discussing AI research strategy.

Read on LessWrong (AI tag) →

AI-generated summary · Google Gemini · from 1 sources. How we write summaries →
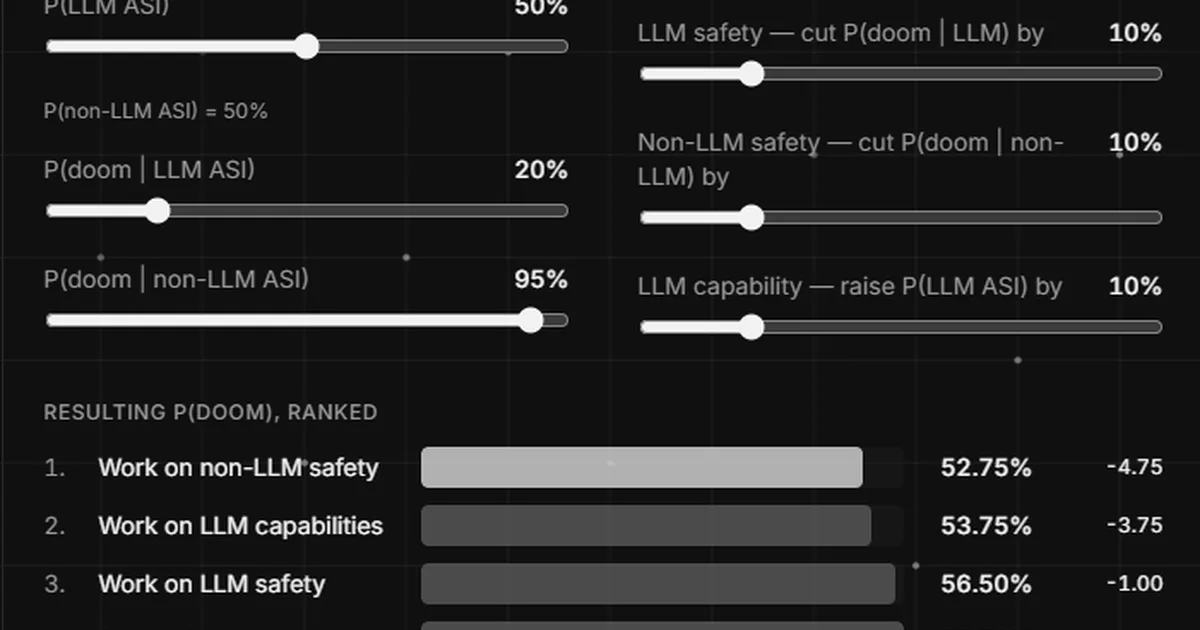
AI capabilities research seen as a rational safety bet

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Commentary
Opinion piece discussing AI research strategy.
Source corroboration
Single-source cluster
Only one publisher covered this so far. Single-source stories can still rank when the publisher is high-authority, but they lack cross-source corroboration.
Topics
opinion, safety
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
90 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [1]

  1. LessWrong (AI tag) TIER_1 English(EN) · RobinHa ·

    When capabilities work is the *safe* bet

    <p><span>If you believe that LLMs lend themselves unusually well to alignment compared to other regimes, this can be a very good reason to start doing capability research on them rather than LLM safety research. Imagine you have these beliefs about how AI goes:</span></p><div></d…