PulseAugur
EN
LIVE 02:58:56

Fireworks AI launches GLM 5.2 Fast for higher inference speeds · 2 sources tracked

Fireworks AI has released a faster version of the GLM 5.2 model, named GLM 5.2 Fast. This new iteration offers the same quality as the standard GLM 5.2 but achieves significantly higher inference speeds, reaching up to 140 tokens per second. The company also highlighted custom deployment options for even greater performance, noting speeds of 446 tokens per second on Artificial Analysis. AI

IMPACT Increases inference speed for LLMs, potentially lowering costs and improving real-time application performance.

RANK_REASON Model release from a frontier AI lab. [lever_c_demoted from frontier_release: ic=2 ai=1.0]

Read on X — Fireworks (inference infra) →

AI-generated summary · Google Gemini · from 2 sources. How we write summaries →
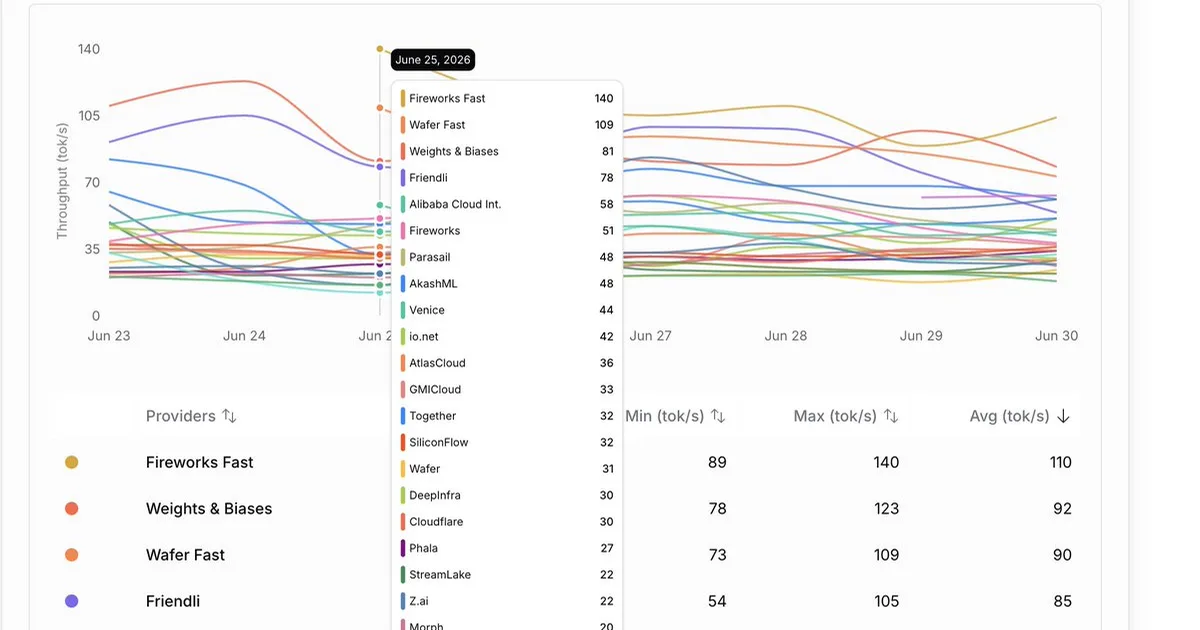
Fireworks AI launches GLM 5.2 Fast for higher inference speeds · 2 sources tracked

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Significant
Model release from a frontier AI lab. [lever_c_demoted from frontier_release: ic=2 ai=1.0]
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
model release, infra
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
98 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [2]

  1. X — Fireworks (inference infra) TIER_1 English(EN) · FireworksAI_HQ ·

    For even higher speeds, reach out for a custom deployment!

    For even higher speeds, reach out for a custom deployment! We’ve hit 446 tok/s on Artificial Analysis. Learn more → https://t.co/rpFJ2dIZvX

  2. X — Fireworks (inference infra) TIER_1 English(EN) · FireworksAI_HQ ·

    We heard your feedback. You want to go faster.

    We heard your feedback. You want to go faster. Introducing GLM 5.2 Fast The same model and quality as GLM 5.2 standard, now at 140 tok/s Flip one model ID → accounts/fireworks/routers/glm-5p2-fast https://t.co/jaYWA4lPi0