PulseAugur
EN
LIVE 20:42:04

Local LLM Agents Benchmark: Framework Outperforms Model on RTX 3090

A benchmark study evaluated five local LLM models on an RTX 3090 GPU, focusing on their performance with different orchestration frameworks. The study found that the choice of framework, particularly one supporting native tool-calling like LangGraph, significantly impacts model effectiveness, with one model improving from a 0% success rate to 93% when using the appropriate agent. The research also highlighted the importance of tool adherence and measured the electricity cost per correct task, identifying Qwen3-Coder as an efficient and effective model for local agent tasks. AI

IMPACT Highlights the critical role of agent orchestration in unlocking LLM potential for local applications.

RANK_REASON Benchmark study comparing LLM models and orchestration frameworks.

Read on dev.to — LLM tag →

AI-generated summary · Google Gemini · from 2 sources. How we write summaries →
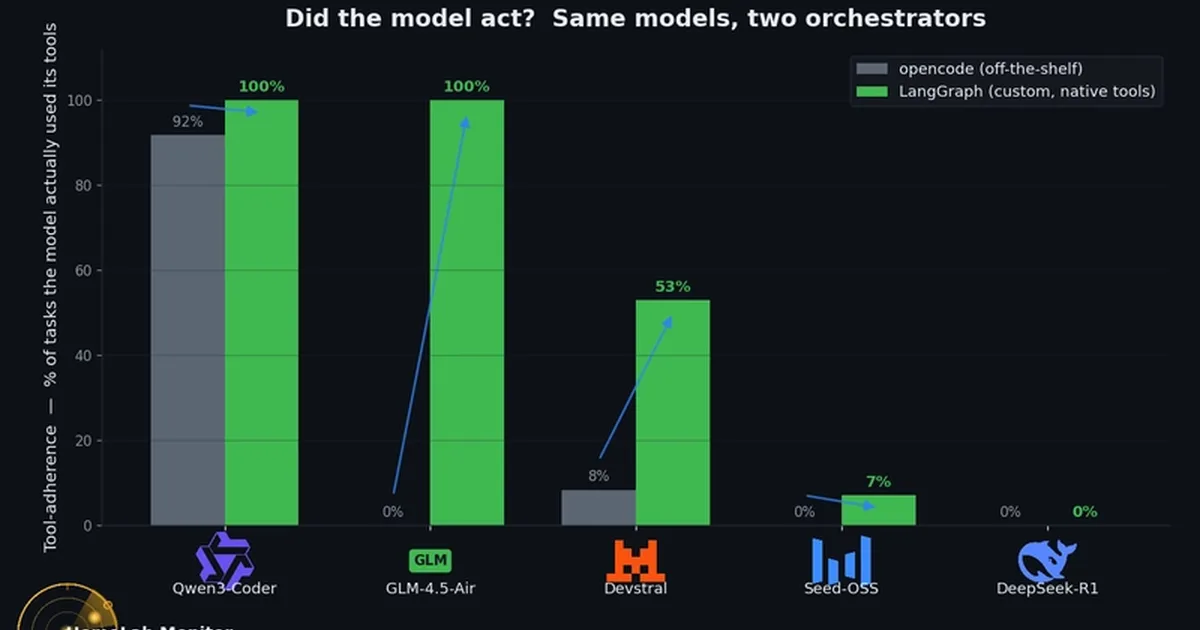
Local LLM Agents Benchmark: Framework Outperforms Model on RTX 3090

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
Benchmark study comparing LLM models and orchestration frameworks.
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
infra, product
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
117 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [2]

  1. Mastodon — fosstodon.org TIER_1 English(EN) · [email protected] ·

    How to Run Reliable Local LLM Agents on an RTX 3090: A Benchmark (5 Models, Priced in Watts) I gave GLM-4.5-Air (106B, open weights) 12 coding tasks through ope

    How to Run Reliable Local LLM Agents on an RTX 3090: A Benchmark (5 Models, Priced in Watts) I gave GLM-4.5-Air (106B, open weights) 12 coding tasks through opencode on my RTX 3090. It scored 0% ... #llm #homelab #opensource #ai Origin | Interest | Match

  2. dev.to — LLM tag TIER_1 English(EN) · Arsen Apostolov ·

    How to Run Reliable Local LLM Agents on an RTX 3090: A Benchmark (5 Models, Priced in Watts)

    <p>I gave <strong>GLM-4.5-Air</strong> (106B, open weights) 12 coding tasks through <a href="https://opencode.ai" rel="noopener noreferrer">opencode</a> on my RTX 3090. It scored <strong>0%</strong> — never edited a single file.</p> <p>Same model, same GPU, same tasks, but driven…