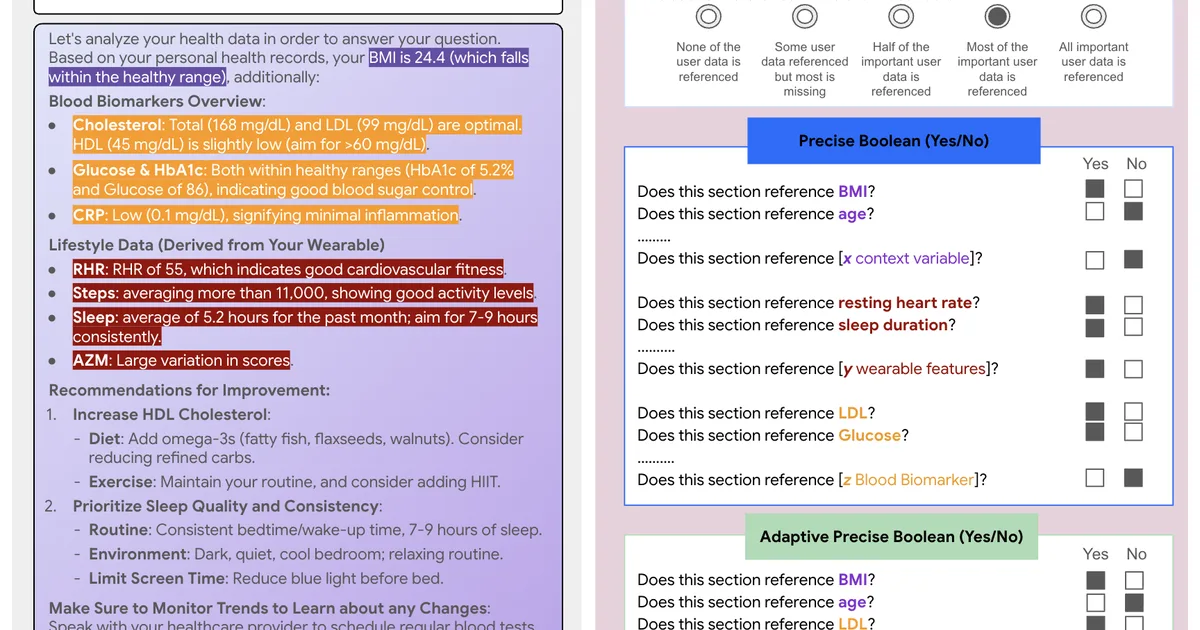
Researchers have developed AfriMed-QA, a new benchmark dataset for evaluating large language models (LLMs) on African health question-answering tasks. This dataset, created in collaboration with African organizations and supported by the Gates Foundation, includes consumer queries and medical school exam questions from 16 African countries. Separately, a new adaptive and precise rubric methodology has been introduced to streamline the evaluation of health language models, aiming to improve scalability and inter-rater reliability. Additionally, a study explored using LLMs to generate synthetic survey responses for public health modeling, finding that while LLMs can reproduce demographic and behavioral patterns, the synthetic data remains identifiable and is not yet a substitute for real survey data. AI
IMPACT These advancements in LLM evaluation and dataset creation are crucial for developing more equitable and effective AI tools for global health applications.
RANK_REASON The cluster consists of research papers introducing new datasets and evaluation methodologies for LLMs in the health domain.
Read on Google AI / Research →
- alphaXiv
- arXiv
- CatalyzeX
- DagsHub
- FluPaths
- Gotit.pub
- Hugging Face
- large language models
- ScienceCast
- ACL 2025
- AfriMed-QA
- Ahmed A. Metwally
- Daniel McDuff
- Google Research
- MedGemma
- njp Digital Medicine
- PATH/The Gates Foundation
AI-generated summary · Google Gemini · from 3 sources. How we write summaries →