PulseAugur
EN
LIVE 18:19:55

Optimizing Transformer Inference: Techniques for Faster, Cheaper Large Models

Large transformer models present significant inference challenges due to their substantial memory footprint and computation costs, which scale quadratically with input length. Researchers and practitioners are exploring various optimization techniques to mitigate these issues. These methods include network compression strategies like pruning, quantization, and knowledge distillation, as well as architectural improvements and efficient parallelism. The goal is to reduce memory usage, computation complexity, and inference latency for practical, large-scale deployment. AI

RANK_REASON The cluster focuses on a technical blog post and a Reddit discussion detailing methods for optimizing transformer model inference, which falls under research and development rather than a new release or significant industry event.

Read on Lil'Log (Lilian Weng) →

AI-generated summary · Google Gemini · from 4 sources. How we write summaries →
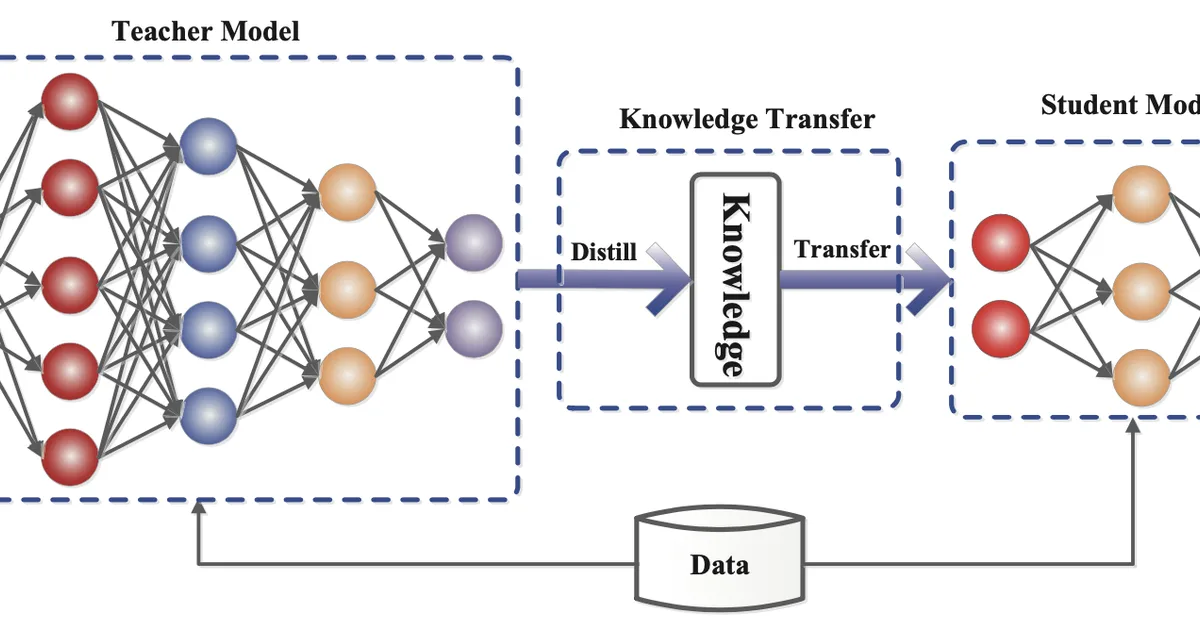
Optimizing Transformer Inference: Techniques for Faster, Cheaper Large Models

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
The cluster focuses on a technical blog post and a Reddit discussion detailing methods for optimizing transformer model inference, which falls under research and development rather than a new relea…
Source corroboration
4 independent sources
Strong cross-source corroboration — multiple independent publishers covered this within the clustering window.
Topics
paper, infra
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
2077 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [4]

  1. Lil'Log (Lilian Weng) TIER_1 English(EN) ·

    Large Transformer Model Inference Optimization

    <p><span class="update">[Updated on 2023-01-24: add a small section on <a href="#distillation">Distillation</a>.]</span><br /></p> <p>Large transformer models are mainstream nowadays, creating SoTA results for a variety of tasks. They are powerful but very expensive to train and …

  2. Hugging Face Blog TIER_1 English(EN) ·

    Accelerated Inference with Optimum and Transformers Pipelines

  3. Hugging Face Blog TIER_1 English(EN) ·

    How we sped up transformer inference 100x for 🤗 API customers

  4. r/MachineLearning TIER_1 English(EN) · /u/Fragrant_Rate_2583 ·

    Optimizing Transformer model size & inference beyond FP16 + ONNX (pruning/graph opt didn’t help much) [P]

    <!-- SC_OFF --><div class="md"><p>Hi everyone, I’ve been working on optimizing a transformer-based neural network for both inference speed and model size, but I feel like I’ve hit a plateau and would appreciate some guidance. So far I’ve converted weights to FP16 (about 2× size r…