PulseAugur
EN
LIVE 10:07:02

LLM inference speed-ups explained with KV cache coding tutorials

The KV cache is a crucial technique for optimizing the inference speed of Large Language Models (LLMs) in production environments. It works by storing and reusing intermediate key and value computations, thereby avoiding redundant calculations during text generation. While it increases memory requirements and code complexity, the significant inference speed-ups often make it a worthwhile trade-off for deploying LLMs. AI

RANK_REASON This is a technical tutorial explaining a fundamental LLM concept with a code implementation.

Read on Ahead of AI (Sebastian Raschka) →

AI-generated summary · Google Gemini · from 2 sources. How we write summaries →
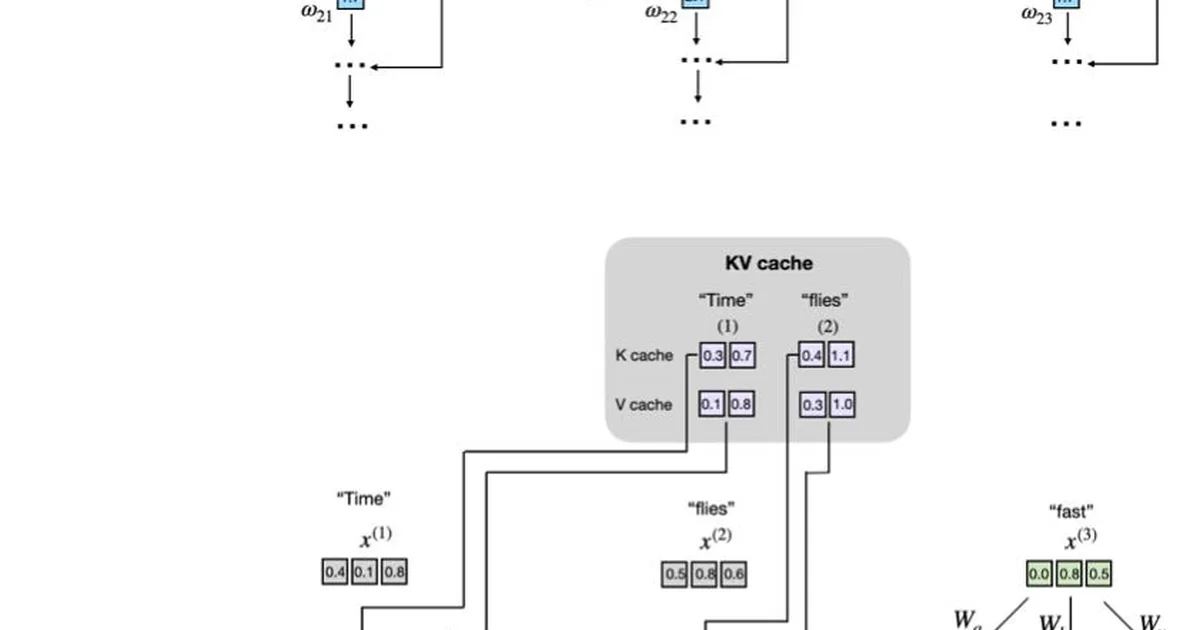
LLM inference speed-ups explained with KV cache coding tutorials

How we ranked this

Signal score
0 / 100
Composite score across the factors below. Higher = stronger signal that this story matters right now.
Newsworthiness bucket
Research
This is a technical tutorial explaining a fundamental LLM concept with a code implementation.
Source corroboration
2 independent sources
Multiple independent publishers reporting the same story raises confidence that it's real and newsworthy.
Topics
paper, other
Editorial topic classification. Feeds into how the story surfaces on /topic/<slug> hub pages and into the per-entity coverage mix.
AI-industry relevance
High
Clearly on-topic for AI-industry coverage.
Story freshness
505 days old
Aged out of breaking-news scoring windows; ranking reflects the durable signal from the full source set.

Full methodology in our editorial standards.

COVERAGE [2]

  1. Hugging Face Blog TIER_1 English(EN) ·

    KV Cache from scratch in nanoVLM

  2. Ahead of AI (Sebastian Raschka) TIER_1 English(EN) · Sebastian Raschka, PhD ·

    Understanding and Coding the KV Cache in LLMs from Scratch

    KV caches are one of the most critical techniques for efficient inference in LLMs in production.